AI for business · Practical guide
Describe a failure so someone else can investigate it.
 By Eric Muriel2 min read
“The automation is broken” leaves many questions open. Turn a fictional failure into a record that supports investigation and a later recovery check.
What you will find
- Start with observations
- Separate known and unconfirmed impact
- Separate evidence from hypotheses
- Define how you will verify recovery
01Start with observations
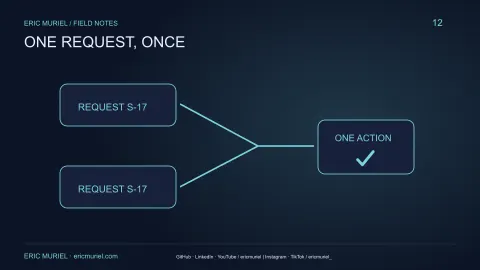
Example: request S-17 is marked received, but its draft cannot be found in the review queue. Expected: a draft associated with S-17. Observed: a recorded input without a located output.
Record observation time, environment and identifier. If the start time is unknown, say so. The first observation does not establish when the failure began.
02Separate known and unconfirmed impact
Inspect some nearby requests without changing their data. Record which have outputs and which do not. One failed request does not establish that every request is affected.
Before repeating operations, check for partial effects: the draft may exist elsewhere or a record may already have changed. Agree with the owner how to avoid duplicates during investigation.
03Separate evidence from hypotheses
Evidence: history shows an error at creation. Hypothesis: destination access might be missing. Pending check: inspect that connection’s permissions. Do not label the hypothesis as the cause before checking it.
Share only data needed for investigation. Replace request content with a fictional example if it reproduces the problem. Keep keys and personal information out of the shared record.
04Define how you will verify recovery
Test a new fictional request and check its draft. Then review affected work using the agreed procedure. Recovering earlier inputs and accepting new ones are different checks.
Close with confirmed impact, cause if known, change made, recovery evidence and outstanding work. If the cause remains unknown, say so; observed recovery does not require an invented explanation.
Frequently asked questions
Should I restart the workflow immediately?
First inspect its state and possible partial effects using the team’s procedure. Restarting without review can obscure investigation or repeat completed work.
Sources (1)
- Monitoring the status of your service · GOV.UK Service Manual — Detect and record service problems.